- Designing a Scalable & Fault-Tolerant Log Pipeline [Part 2]: The Buffer Layer
Whether you actually need Kafka, what a buffer layer makes possible, and how to configure it correctly for log pipelines at scale.
7 min read - Designing a Scalable & Fault-Tolerant Log Pipeline [Part 1]: Agents and Forwarders
How to split responsibilities between log agents and forwarders, what each layer must handle, and three deployment patterns for log pipelines at scale.
4 min read -
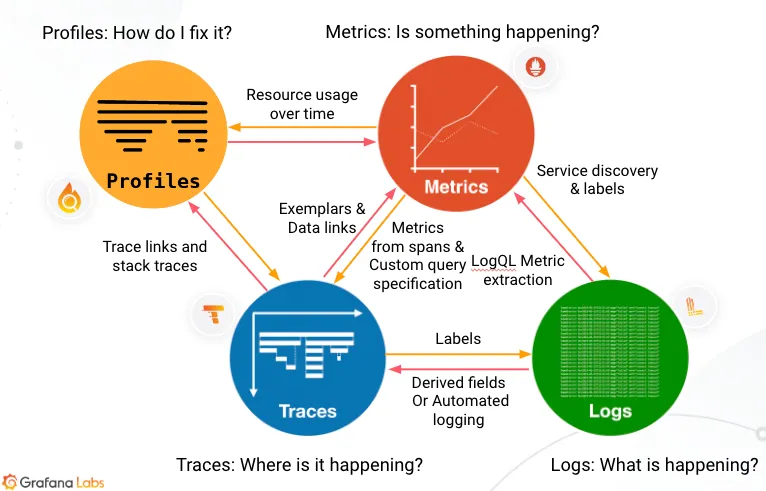 Correlating Telemetry in Grafana: From Metrics to Logs to Traces
How to navigate from a firing alert to a root cause using Grafana, Tempo, Loki, OpenSearch, and Prometheus
10 min read -
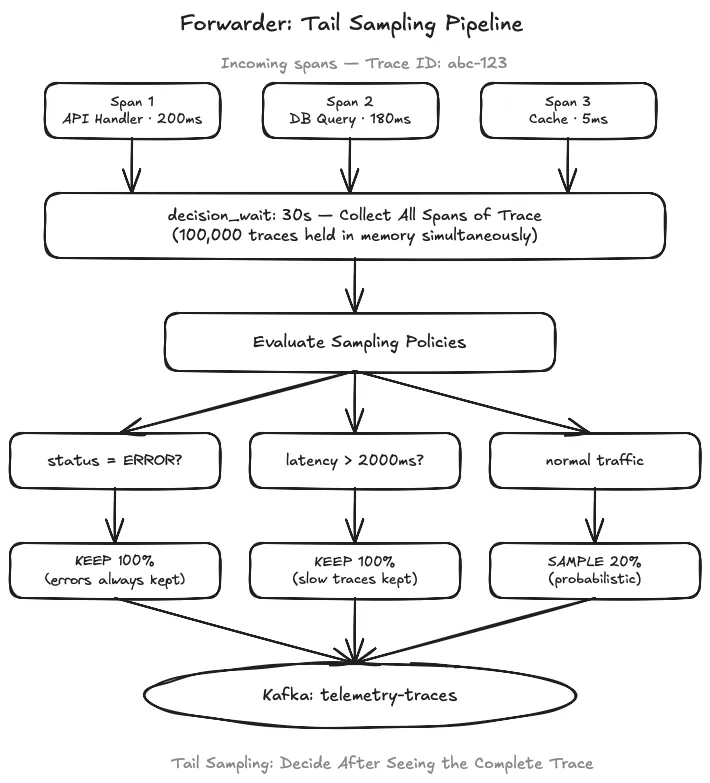 Designing a Telemetry Pipeline That Scales [Part 2]: Sampling, Kafka, Storage, and HA
How to make the pipeline durable at scale with tail sampling, Kafka buffering, VictoriaMetrics, Tempo, and production hardening.
14 min read -
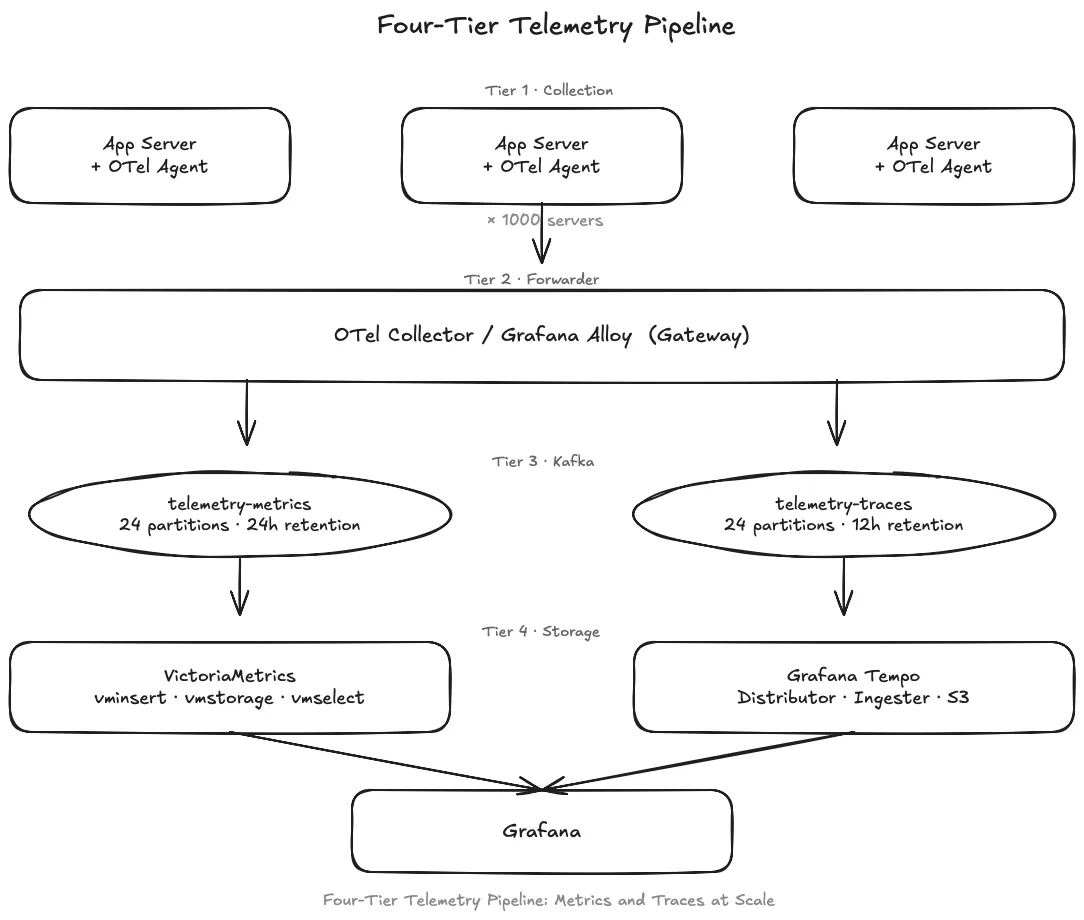 Designing a Telemetry Pipeline That Scales [Part 1]: Architecture, Agents, and Forwarders
Why observability pipelines fail at 100 to 1,000 servers, and how to redesign collection and processing with OpenTelemetry.
26 min read